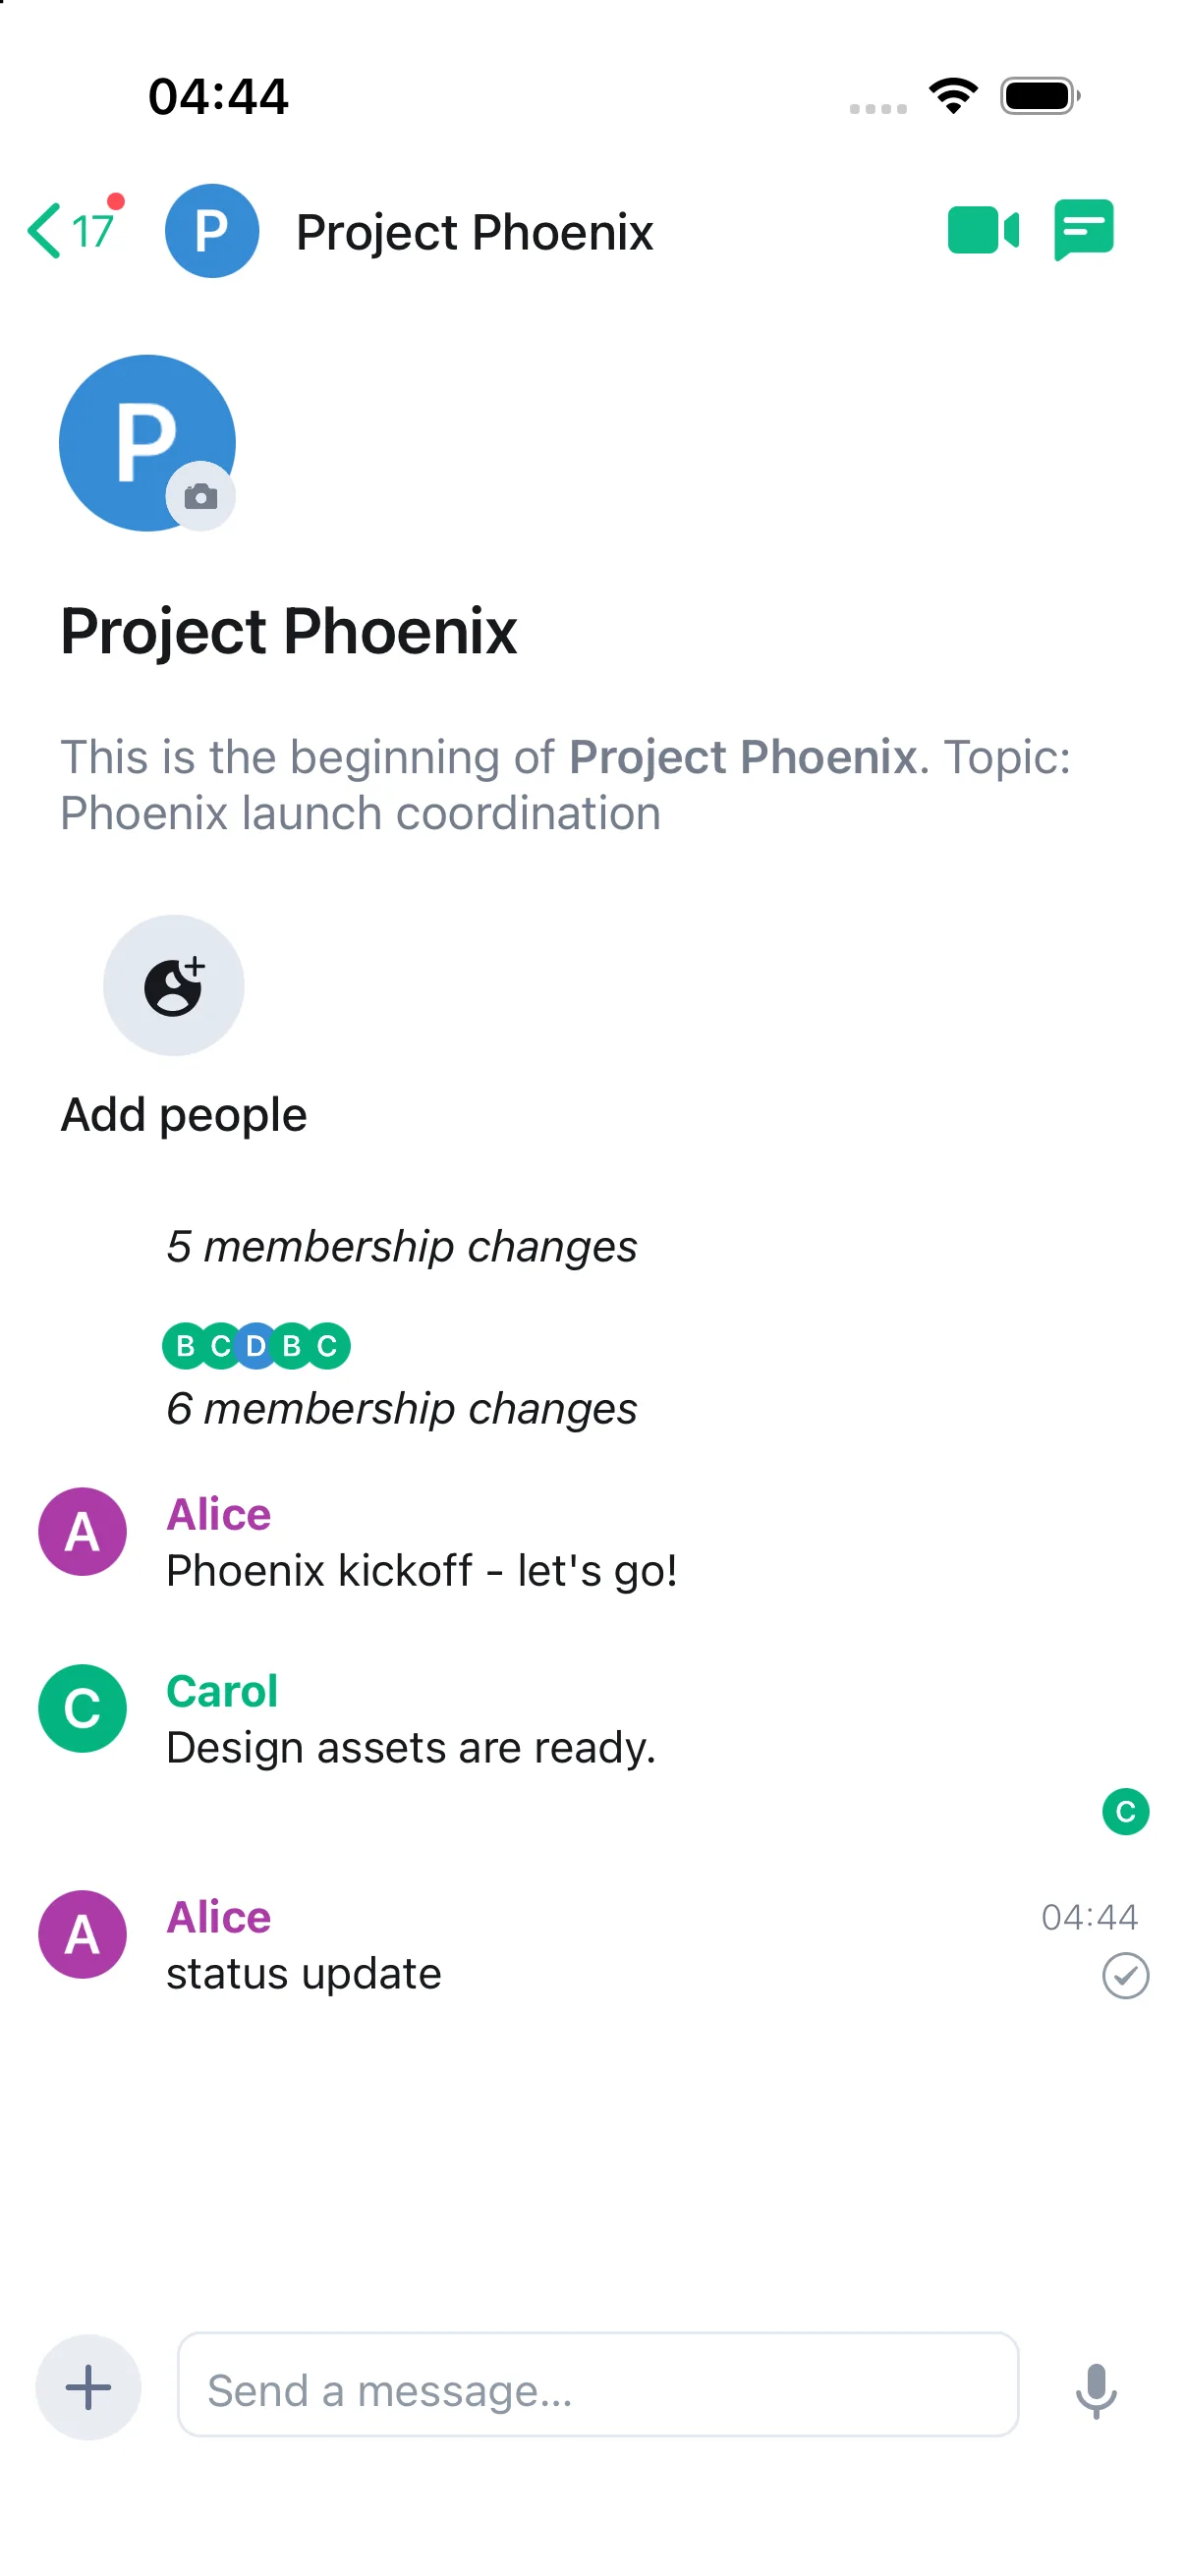
Open the "Project Phoenix" room and send the message "status update".
success1.0
The final screenshot shows the Project Phoenix room with Alice's sent message 'status update' visible with timestamp/checkmark and an empty composer.
Created by
Compare models, tools, cost, and test runs across real iOS app-control tasks.
Completion assigns 1 to success, 0.5 to partial, and 0 to failure. Ties are broken by mean time on successful runs.
| Rank | Configuration | Tool | Completion | Time / run | Cost / run | Task outcomes |
|---|---|---|---|---|---|---|
| 01 | qwen3.8-max (high)· argent v0.15.0 | argentv0.15.0 | 98.3% | 2m 51s | $0.32 | Passed 97%, Partial 3%, Failed 0% Time / run2m 51sCost / run$0.32 |
| 02 | haiku-4.5 (high)· argent v0.15.0 | argentv0.15.0 | 97.5% | 1m 07s | $0.22 | Passed 95%, Partial 5%, Failed 0% Time / run1m 07sCost / run$0.22 |
| 03 | qwen3.8-max (low)· argent v0.15.0 | argentv0.15.0 | 95.8% | 1m 14s | $0.27 | Passed 93%, Partial 5%, Failed 2% Time / run1m 14sCost / run$0.27 |
| 04 | gpt-5.4-mini (high)· argent v0.15.0 | argentv0.15.0 | 95.0% | 1m 14s | $0.13 | Passed 92%, Partial 7%, Failed 2% Time / run1m 14sCost / run$0.13 |
| 05 | haiku-4.5 (low)· argent v0.15.0 | argentv0.15.0 | 94.2% | 58s | $0.20 | Passed 92%, Partial 5%, Failed 3% Time / run58sCost / run$0.20 |
| 06 | qwen3.8-max (high)· agent-device v0.17.6 | agent-devicev0.17.6 | 92.5% | 3m 20s | $0.23 | Passed 88%, Partial 8%, Failed 3% Time / run3m 20sCost / run$0.23 |
| 07 | qwen3.8-max (low)· agent-device v0.17.6 | agent-devicev0.17.6 | 89.2% | 2m 51s | $0.26 | Passed 83%, Partial 12%, Failed 5% Time / run2m 51sCost / run$0.26 |
| 08 | gpt-5.4-mini (high)· agent-device v0.17.6 | agent-devicev0.17.6 | 85.0% | 1m 29s | $0.10 | Passed 77%, Partial 17%, Failed 7% Time / run1m 29sCost / run$0.10 |
| 09 | haiku-4.5 (low)· agent-device v0.17.6 | agent-devicev0.17.6 | 84.2% | 1m 53s | $0.13 | Passed 80%, Partial 8%, Failed 12% Time / run1m 53sCost / run$0.13 |
| 10 | haiku-4.5 (high)· agent-device v0.17.6 | agent-devicev0.17.6 | 83.3% | 1m 25s | $0.15 | Passed 75%, Partial 17%, Failed 8% Time / run1m 25sCost / run$0.15 |
| model | argentv0.15.0 | agent-devicev0.17.6 | no tool |
|---|---|---|---|
| gpt-5.4-mini | 88.8%n=120 | 83.8%n=120 | 30.8%n=120 |
| low | 82.5%n=60 | 82.5%n=60 | 15.8%n=60 |
| high | 95.0%n=60 | 85.0%n=60 | 45.8%n=60 |
| haiku-4.5 | 95.8%n=120 | 83.8%n=120 | 13.3%n=120 |
| low | 94.2%n=60 | 84.2%n=60 | 15.0%n=60 |
| high | 97.5%n=60 | 83.3%n=60 | 11.7%n=60 |
| qwen3.8-max | 97.1%n=120 | 90.8%n=120 | 57.5%n=120 |
| low | 95.8%n=60 | 89.2%n=60 | 53.3%n=60 |
| high | 98.3%n=60 | 92.5%n=60 | 61.7%n=60 |
| overall | 93.9%n=360 | 86.1%n=360 | 33.9%n=360 |
Open the "Project Phoenix" room and send the message "status update".
The final screenshot shows the Project Phoenix room with Alice's sent message 'status update' visible with timestamp/checkmark and an empty composer.
The judge is never told which model produced a screenshot, though the action names reveal which tool drove the device.